You have a Fabric warehouse named DW1. DW1 contains a table that stores sales data and is used by multiple sales representatives.
You plan to implement row-level security (RLS).
You need to ensure that the sales representatives can see only their respective data.
Which warehouse object do you require to implement RLS?
A. SECURITY POLICY
B. TABLE
C. TRIGGER
D. STORED PROCEDURE
Show Answer
Correct Answer: A
Explanation: The required warehouse object to enforce row-level security is a SECURITY POLICY. In Microsoft Fabric Warehouse, RLS is implemented by creating a predicate function and then binding it to the target table through a SECURITY POLICY. Since the function is not an answer option, the required object from the choices is SECURITY POLICY.
Question 26
You have a Fabric warehouse named DW1. DW1 contains a table that stores sales data and is used by multiple sales representatives.
You plan to implement row-level security (RLS).
You need to ensure that the sales representatives can see only their respective data.
Which warehouse object do you require to implement RLS?
A. TRIGGER
B. SCHEMA
C. FUNCTION
D. DATABASE ROLE
Show Answer
Correct Answer: C
Explanation: Row-level security in a Fabric warehouse is implemented by defining a predicate function that filters rows based on the executing user's identity, and then applying it through a security policy. Among the available options, the required warehouse object is a FUNCTION. A database role controls permissions but does not implement dynamic row filtering.
Question 26
You have a Fabric workspace named Workspace1 that contains a notebook named Notebook1.
In Workspace1, you create a new notebook named Notebook2.
You need to ensure that you can attach Notebook2 to the same Apache Spark session as Notebook1.
What should you do?
A. Enable high concurrency for notebooks.
B. Enable dynamic allocation for the Spark pool.
C. Change the runtime version.
D. Increase the number of executors.
Show Answer
Correct Answer: A
Explanation: Enable high concurrency for notebooks. This allows multiple notebooks to attach to and share the same Apache Spark session; changing the runtime or executor settings does not enable session sharing.
Question 27
HOTSPOT
-
Case Study
-
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
-
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview. Company Overview
-
Contoso, Ltd. is an online retail company that wants to modernize its analytics platform by moving to Fabric. The company plans to begin using Fabric for marketing analytics.
Overview. IT Structure
-
The company’s IT department has a team of data analysts and a team of data engineers that use analytics systems.
The data engineers perform the ingestion, transformation, and loading of data. They prefer to use Python or SQL to transform the data.
The data analysts query data and create semantic models and reports. They are qualified to write queries in Power Query and T-SQL.
Existing Environment. Fabric
-
Contoso has an F64 capacity named Cap1. All Fabric users are allowed to create items.
Contoso has two workspaces named WorkspaceA and WorkspaceB that currently use Pro license mode.
Existing Environment. Source Systems
Contoso has a point of sale (POS) system named POS1 that uses an instance of SQL Server on Azure Virtual Machines in the same Microsoft Entra tenant as Fabric. The host virtual machine is on a private virtual network that has public access blocked. POS1 contains all the sales transactions that were processed on the company’s website.
The company has a software as a service (SaaS) online marketing app named MAR1. MAR1 has seven entities. The entities contain data that relates to email open rates and interaction rates, as well as website interactions. The data can be exported from MAR1 by calling REST APIs. Each entity has a different endpoint.
Contoso has been using MAR1 for one year. Data from prior years is stored in Parquet files in an Amazon Simple Storage Service (Amazon S3) bucket. There are 12 files that range in size from 300 MB to 900 MB and relate to email interactions.
Existing Environment. Product Data
POS1 contains a product list and related data. The data comes from the following three tables:
• Products
• ProductCategories
• ProductSubcategories
In the data, products are related to product subcategories, and subcategories are related to product categories.
Existing Environment. Azure
-
Contoso has a Microsoft Entra tenant that has the following mail-enabled security groups:
• DataAnalysts: Contains the data analysts
• DataEngineers: Contains the data engineers
Contoso has an Azure subscription.
The company has an existing Azure DevOps organization and creates a new project for repositories that relate to Fabric.
Existing Environment. User Problems
The VP of marketing at Contoso requires analysis on the effectiveness of different types of email content. It typically takes a week to manually compile and analyze the data. Contoso wants to reduce the time to less than one day by using Fabric.
The data engineering team has successfully exported data from MAR1. The team experiences transient connectivity errors, which causes the data exports to fail.
Requirements. Planned Changes
-
Contoso plans to create the following two lakehouses:
• Lakehouse1: Will store both raw and cleansed data from the sources
• Lakehouse2: Will serve data in a dimensional model to users for analytical queries
Additional items will be added to facilitate data ingestion and transformation.
Contoso plans to use Azure Repos for source control in Fabric.
Requirements. Technical Requirements
The new lakehouses must follow a medallion architecture by using the following three layers: bronze, silver, and gold. There will be extensive data cleansing required to populate the MAR1 data in the silver layer, including deduplication, the handling of missing values, and the standardizing of capitalization.
Each layer must be fully populated before moving on to the next layer. If any step in populating the lakehouses fails, an email must be sent to the data engineers.
Data imports must run simultaneously, when possible.
The use of email data from the Amazon S3 bucket must meet the following requirements:
• Minimize egress costs associated with cross-cloud data access.
• Prevent saving a copy of the raw data in the lakehouses.
Items that relate to data ingestion must meet the following requirements:
• The items must be source controlled alongside other workspace items.
• Ingested data must land in the bronze layer of Lakehouse1 in the Delta format.
• No changes other than changes to the file formats must be implemented before the data lands in the bronze layer.
• Development effort must be minimized and a built-in connection must be used to import the source data.
• In the event of a connectivity error, the ingestion processes must attempt the connection again.
Lakehouses, data pipelines, and notebooks must be stored in WorkspaceA. Semantic models, reports, and dataflows must be stored in WorkspaceB.
Once a week, old files that are no longer referenced by a Delta table log must be removed.
Requirements. Data Transformation
In the POS1 product data, ProductID values are unique. The product dimension in the gold layer must include only active products from product list. Active products are identified by an IsActive value of 1.
Some product categories and subcategories are NOT assigned to any product. They are NOT analytically relevant and must be omitted from the product dimension in the gold layer.
Requirements. Data Security
-
Security in Fabric must meet the following requirements:
• The data engineers must have read and write access to all the lakehouses, including the underlying files.
• The data analysts must only have read access to the Delta tables in the gold layer.
• The data analysts must NOT have access to the data in the bronze and silver layers.
• The data engineers must be able to commit changes to source control in WorkspaceA.
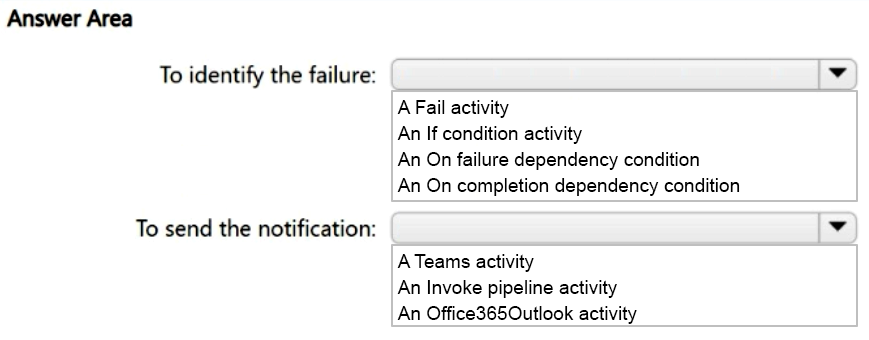
You need to ensure that the data engineers are notified if any step in populating the lakehouses fails. The solution must meet the technical requirements and minimize development effort.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Show Answer
Correct Answer: To identify the failure:
An On failure dependency condition
To send the notification:
An Office365Outlook activity
Explanation: Use an On failure dependency condition so the notification runs only when a preceding pipeline activity fails. The requirement explicitly states an email must be sent, so the Office365Outlook activity is the built-in choice with minimal development effort.
Question 28
HOTSPOT
-
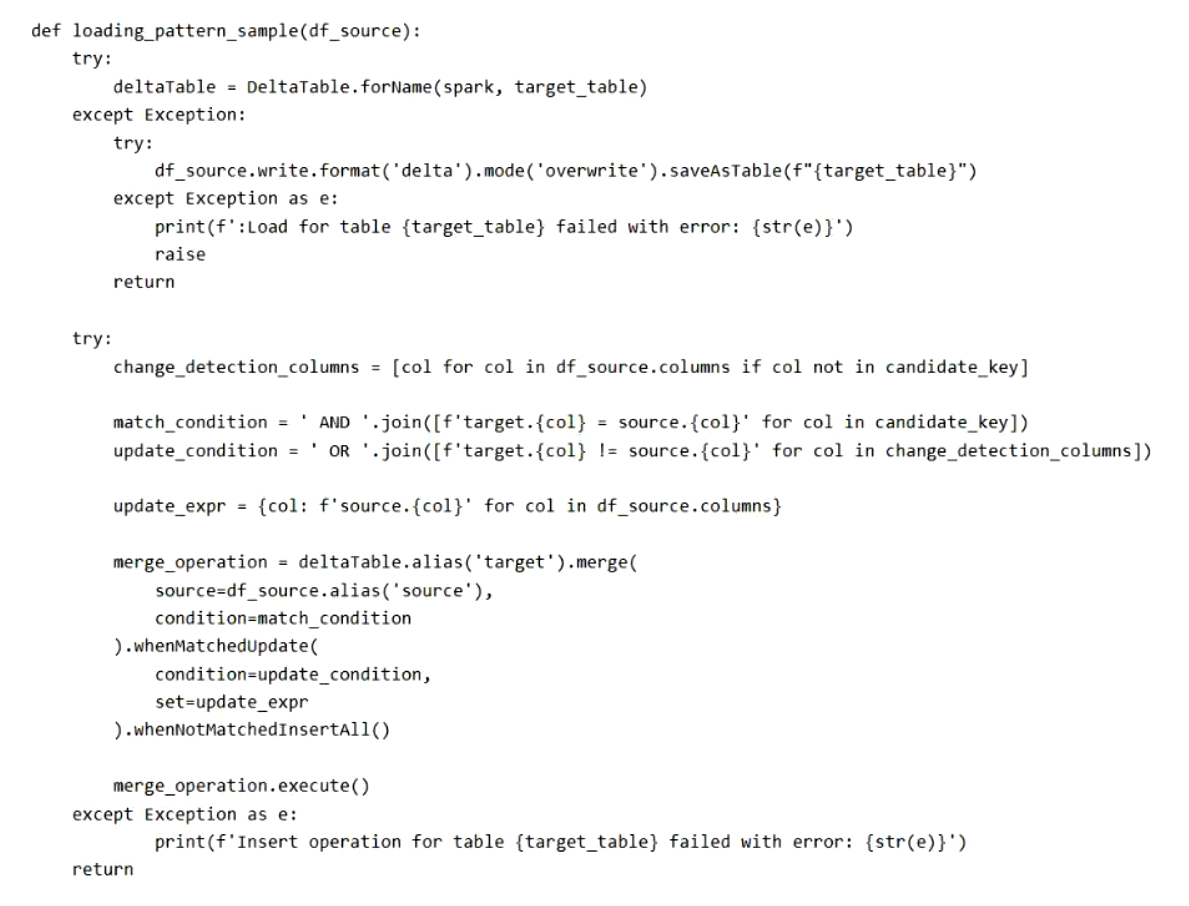
You are building a data loading pattern for Fabric notebook workloads.
You have the following code segment.
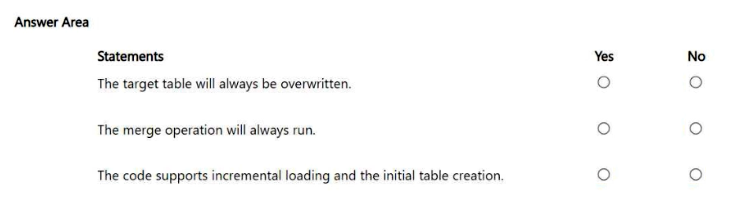
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Show Answer
Correct Answer: 1. No
2. No
3. Yes
Explanation: The table is only overwritten during initial creation if it does not exist. The merge does not always run because a failure during table creation re-raises the exception and exits. The pattern supports initial table creation and subsequent incremental MERGE-based upserts.
Question 29
Case Study -
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study -
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview -
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide. Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse. Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen2 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
• Sales Date
• Author
• Price
• Units
• SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
• Sales
• Fabric Admins
• Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: “The SQL query failed while running.”
The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company’s sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes -
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control -
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements -
Litware identifies the following data requirements:
• Process the SEO data in near-real-time (NRT).
• Make the book reviews available in the lakehouse without making a copy of the data.
• When a new book cover image arrives in the Files folder, process the image as soon as possible.
You need to create a workflow for the new book cover images.
Which two components should you include in the workflow? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
A. an activator item
B. a data pipeline
C. a blob storage action
D. a time-based schedule
E. a streaming dataflow
F. a notebook that uses Apache Spark Structured Streaming
Show Answer
Correct Answer: A, B
Explanation: Use an Activator item to detect the arrival of new book cover images and trigger automation. A Data Pipeline orchestrates the processing workflow (for example, invoking a notebook or other Fabric activities). A time-based schedule does not satisfy the requirement to process images as soon as possible, blob storage actions would rely on Azure resources rather than a Fabric-only workflow, streaming dataflows are intended for streaming data rather than file arrival events, and Structured Streaming is not the appropriate trigger mechanism for newly landed image files.
Question 30
You have an Azure event hub. Each event contains the following fields:
• BikepointID
• Street
• Neighbourhood
• Latitude
• Longitude
• No_Bikes
• No_Empty_Docks
You need to ingest the events. The solution must only retain events that have a Neighbourhood value of Chelsea, and then store the retained events in a Fabric lakehouse.
Data retention in case of failure is required to be two days.
What should you use?
A. an eventstream
B. Apache Spark Structured Streaming
C. a streaming dataset
D. a KQL queryset
Show Answer
Correct Answer: A
Explanation: An eventstream is designed to ingest data from Azure Event Hubs, apply no-code filtering (such as retaining only events where Neighbourhood = 'Chelsea'), and write the filtered stream directly to a Fabric lakehouse. Eventstreams also support configurable retention for failure recovery, so a two-day retention requirement can be met.
Question 32
DRAG DROP
-
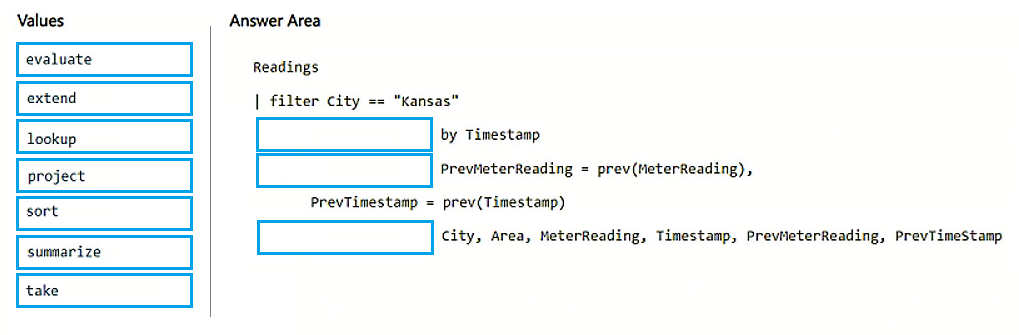
You have a KQL database that contains a table named Readings.
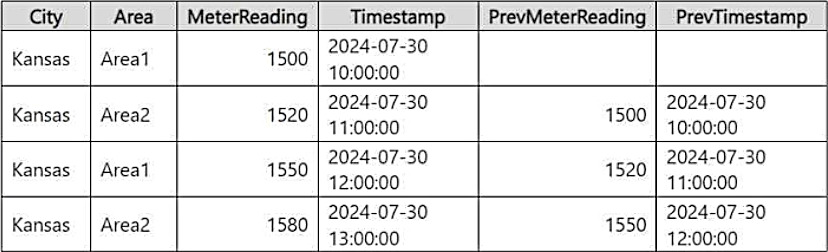
You need to build a KQL query to compare the MeterReading value of each row to the previous row base on the Timestamp value.
A sample of the expected output is shown in the following table.
How should you complete the query? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Show Answer
Correct Answer: sort
extend
project
Explanation: Sort the rows by Timestamp before using prev(). Use extend to create PrevMeterReading and PrevTimestamp with prev(), then project the required output columns. In practice, use 'sort by Timestamp asc' because sort defaults to descending.
Question 33
You have an Azure SQL database named DB1.
In a Fabric workspace, you deploy an eventstream named EventStreamDB1 to stream record changes from DB1 into a lakehouse.
You discover that events are NOT being propagated to EventStreamDB1.
You need to ensure that the events are propagated to EventStreamDB1.
What should you do?
A. Create a read-only replica of DB1.
B. Create an Azure Stream Analytics job.
C. Enable Extended Events for DB1.
D. Enable change data capture (CDC) for DB1.
Show Answer
Correct Answer: D
Explanation: Microsoft Fabric eventstreams use Change Data Capture (CDC) to capture and stream row-level changes from supported Azure SQL databases. If CDC is not enabled on the source database, change events will not be propagated. Creating a read-only replica, enabling Extended Events, or creating an Azure Stream Analytics job does not enable database change capture for this integration.
Question 34
Case Study -
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study -
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview. Company Overview -
Contoso, Ltd. is an online retail company that wants to modernize its analytics platform by moving to Fabric. The company plans to begin using Fabric for marketing analytics.
Overview. IT Structure -
The company’s IT department has a team of data analysts and a team of data engineers that use analytics systems.
The data engineers perform the ingestion, transformation, and loading of data. They prefer to use Python or SQL to transform the data.
The data analysts query data and create semantic models and reports. They are qualified to write queries in Power Query and T-SQL.
Existing Environment. Fabric -
Contoso has an F64 capacity named Cap1. All Fabric users are allowed to create items.
Contoso has two workspaces named WorkspaceA and WorkspaceB that currently use Pro license mode.
Existing Environment. Source Systems
Contoso has a point of sale (POS) system named POS1 that uses an instance of SQL Server on Azure Virtual Machines in the same Microsoft Entra tenant as Fabric. The host virtual machine is on a private virtual network that has public access blocked. POS1 contains all the sales transactions that were processed on the company’s website.
The company has a software as a service (SaaS) online marketing app named MAR1. MAR1 has seven entities. The entities contain data that relates to email open rates and interaction rates, as well as website interactions. The data can be exported from MAR1 by calling REST APIs. Each entity has a different endpoint.
Contoso has been using MAR1 for one year. Data from prior years is stored in Parquet files in an Amazon Simple Storage Service (Amazon S3) bucket. There are 12 files that range in size from 300 MB to 900 MB and relate to email interactions.
Existing Environment. Product Data
POS1 contains a product list and related data. The data comes from the following three tables:
• Products
• ProductCategories
• ProductSubcategories
In the data, products are related to product subcategories, and subcategories are related to product categories.
Existing Environment. Azure -
Contoso has a Microsoft Entra tenant that has the following mail-enabled security groups:
• DataAnalysts: Contains the data analysts
• DataEngineers: Contains the data engineers
Contoso has an Azure subscription.
The company has an existing Azure DevOps organization and creates a new project for repositories that relate to Fabric.
Existing Environment. User Problems
The VP of marketing at Contoso requires analysis on the effectiveness of different types of email content. It typically takes a week to manually compile and analyze the data. Contoso wants to reduce the time to less than one day by using Fabric.
The data engineering team has successfully exported data from MAR1. The team experiences transient connectivity errors, which causes the data exports to fail.
Requirements. Planned Changes -
Contoso plans to create the following two lakehouses:
• Lakehouse1: Will store both raw and cleansed data from the sources
• Lakehouse2: Will serve data in a dimensional model to users for analytical queries
Additional items will be added to facilitate data ingestion and transformation.
Contoso plans to use Azure Repos for source control in Fabric.
Requirements. Technical Requirements
The new lakehouses must follow a medallion architecture by using the following three layers: bronze, silver, and gold. There will be extensive data cleansing required to populate the MAR1 data in the silver layer, including deduplication, the handling of missing values, and the standardizing of capitalization.
Each layer must be fully populated before moving on to the next layer. If any step in populating the lakehouses fails, an email must be sent to the data engineers.
Data imports must run simultaneously, when possible.
The use of email data from the Amazon S3 bucket must meet the following requirements:
• Minimize egress costs associated with cross-cloud data access.
• Prevent saving a copy of the raw data in the lakehouses.
Items that relate to data ingestion must meet the following requirements:
• The items must be source controlled alongside other workspace items.
• Ingested data must land in the bronze layer of Lakehouse1 in the Delta format.
• No changes other than changes to the file formats must be implemented before the data lands in the bronze layer.
• Development effort must be minimized and a built-in connection must be used to import the source data.
• In the event of a connectivity error, the ingestion processes must attempt the connection again.
Lakehouses, data pipelines, and notebooks must be stored in WorkspaceA. Semantic models, reports, and dataflows must be stored in WorkspaceB.
Once a week, old files that are no longer referenced by a Delta table log must be removed.
Requirements. Data Transformation
In the POS1 product data, ProductID values are unique. The product dimension in the gold layer must include only active products from product list. Active products are identified by an IsActive value of 1.
Some product categories and subcategories are NOT assigned to any product. They are NOT analytically relevant and must be omitted from the product dimension in the gold layer.
Requirements. Data Security -
Security in Fabric must meet the following requirements:
• The data engineers must have read and write access to all the lakehouses, including the underlying files.
• The data analysts must only have read access to the Delta tables in the gold layer.
• The data analysts must NOT have access to the data in the bronze and silver layers.
• The data engineers must be able to commit changes to source control in WorkspaceA.
You need to recommend a solution for handling old files. The solution must meet the technical requirements.
What should you include in the recommendation?
A. a data pipeline that includes a Copy data activity
B. a data pipeline that includes a Delete data activity
C. a notebook that runs the VACUUM command
D. a notebook that runs the OPTIMIZE command
Show Answer
Correct Answer: C
Explanation: Delta Lake's VACUUM command removes obsolete data files that are no longer referenced by the Delta transaction log. This directly satisfies the requirement to remove old files no longer referenced by a Delta table log on a scheduled basis. OPTIMIZE compacts files for performance, while Copy data and Delete data pipeline activities do not use Delta transaction log awareness and would require custom logic to identify safe-to-delete files.
$19
Get all 144 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.