You have a Fabric workspace that contains a warehouse named Warehouse1, a lakehouse named lakehouse1, and a semantic model named Model1. Model1 is used by a Microsoft Power BI report.
You need to ensure that if a semantic model refresh fails, an email is sent to the workspace administrator. The solution must minimize development effort.
What should you create?
A. a Fabric pipeline
B. a Data Activator alert
C. a T-SQL trigger for Warehouse1
D. an Apache Spark notebook job
Show Answer
Correct Answer: B
Explanation: Create a Data Activator alert to monitor the semantic model refresh status and notify the workspace administrator when a refresh fails. This is a native, low-code solution and avoids building a custom pipeline or notebook.
Question 6
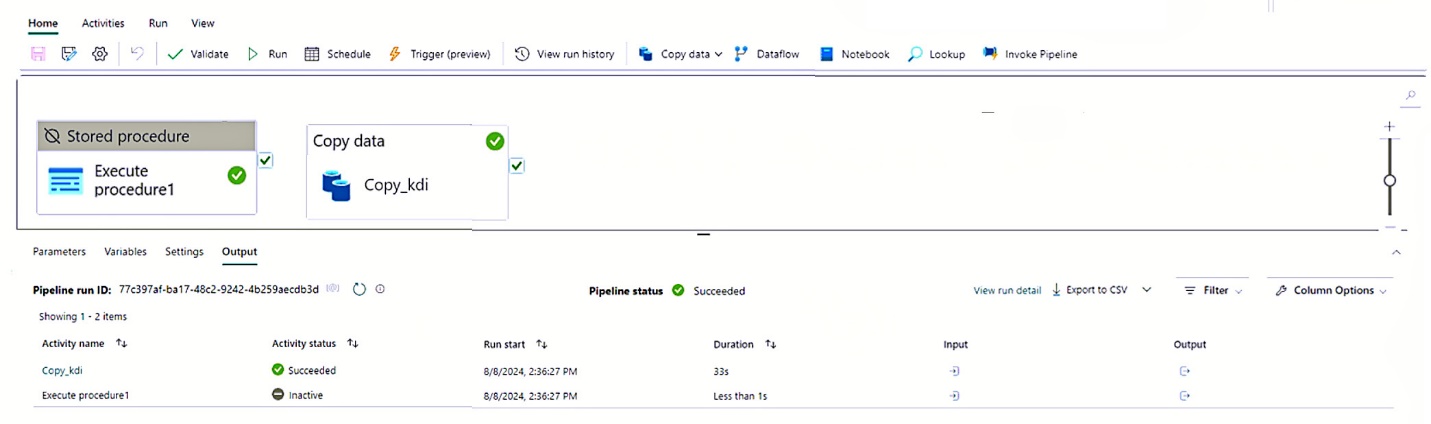
You have a Fabric workspace that contains a data pipeline named Pipeline1 as shown in the exhibit. (Click the Exhibit tab.)
What will occur the next time Pipeline1 runs?
A. Copy_kdi will run first, and then Execute procedure1 will run.
B. Execute procedure1 will run first, and then Copy_kdi will run.
C. Execute procedure1 will run and Copy_kdi will be skipped.
D. Copy_kdi will run and Execute procedure1 will be skipped.
E. Both activities will run simultaneously.
F. Both activities will be skipped.
Show Answer
Correct Answer: D
Explanation: Copy_kdi is active and will run. Execute procedure1 is marked inactive (the crossed-circle icon), so it will be skipped on the next run.
Question 6
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
You perform the following actions:
• Connect Workspace1 to a Git repository and select the main branch.
• Create a new branch named feature1 and modify Lakehouse1.
• Merge the changes from feature1 into the main branch.
You need to ensure that the changes are available in Workspace1. The solution must minimize changes to Workspace1.
What should you do?
A. Disconnect Workspace1 from the Git repository and reconnect Workspace1 to the main branch.
B. From Workspace1, select Source control, and then select Updates.
C. From Workspace1, select Source control, and then select Commit.
D. Switch Workspace1 to the feature1 branch and refresh the workspace.
Show Answer
Correct Answer: B
Explanation: After merging changes from the feature branch into the main branch, the Git repository has newer content than the connected workspace. In Fabric Git integration, selecting Source control > Updates pulls the latest changes from the connected branch (main) into the workspace. This synchronizes the workspace with the merged changes while minimizing changes to the workspace. Committing would push workspace changes to Git, switching branches is unnecessary, and disconnecting/reconnecting is not required.
Question 6
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Lakehouse1 processes data from more than 100 sources by using a medallion architecture. Lakehouse1 ingests the data in batch loads by using Dataflow Gen2.
You need to collect IoT sensor data from connected devices in near-real-time (NRT). The solution must meet the following requirements:
• Generate NRT dashboards and perform anomaly detection.
• Store the streaming data for downstream batch processing into Lakehouse1.
The solution must minimize development effort.
What should you use?
A. Azure Stream Analytics
B. Azure Event Hubs
C. Apache Spark streaming jobs
D. Dataflow Gen2
Show Answer
Correct Answer: A
Explanation: Azure Stream Analytics is designed for near-real-time stream processing and includes built-in anomaly-detection functions. It can also route the processed stream to dashboards and persistent storage for downstream batch processing. Event Hubs is primarily an ingestion service; Spark streaming generally requires more development, and Dataflow Gen2 is intended for batch-oriented dataflows.
Question 7
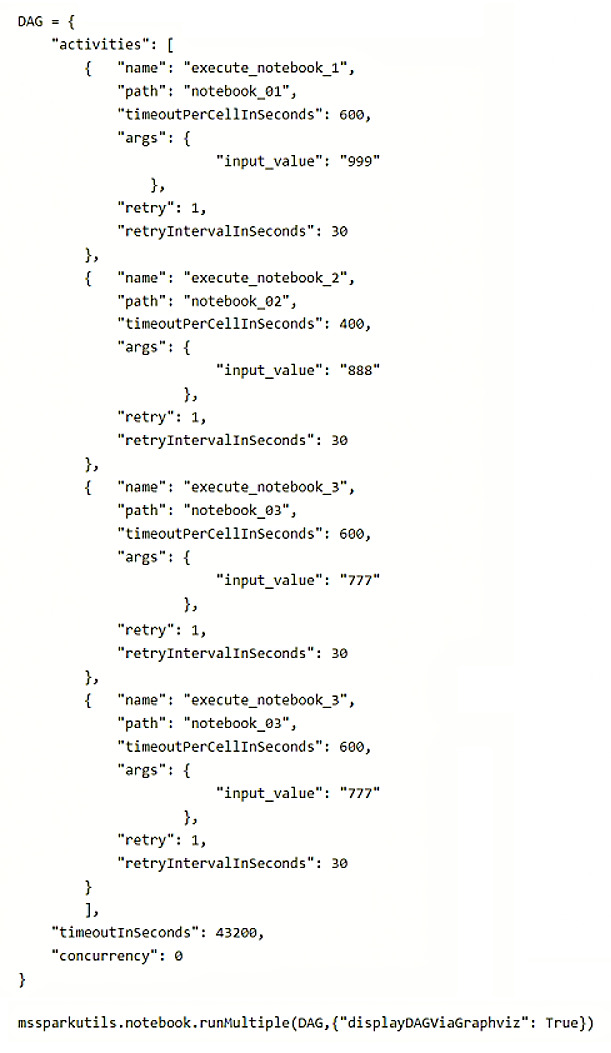
You are building a Fabric notebook named MasterNotebook1 in a workspace. MasterNotebook1 contains the following code.
You need to ensure that the notebooks are executed in the following sequence:
1. Notebook_03
2. Notebook_01
3. Notebook_02
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
A. Move the declaration of Notebook_02 to the bottom of the Directed Acyclic Graph (DAG) definition.
B. Add dependencies to the execution of Notebook_03.
C. Split the Directed Acyclic Graph (DAG) definition into three separate definitions.
D. Add dependencies to the execution of Notebook_02.
E. Change the concurrency to 3.
F. Move the declaration of Notebook_03 to the top of the Directed Acyclic Graph (DAG) definition.
Show Answer
Correct Answer: D
Explanation: No two listed actions ensure the requested sequence. Notebook_02 must depend on Notebook_01 (D), but Notebook_01 must also depend on Notebook_03—an option that is missing. Moving declarations does not control DAG execution order. The code also declares the Notebook_03 activity twice.
Question 7
You have a Fabric workspace named Workspace1 that uses version control. Workspace1 and Azure DevOps are integrated.
In Azure DevOps, developers create a branch named Branch1 to test extract, transform, and load (ETL) updates.
You need to connect Workspace1 to Branch1. The solution must ensure that all the existing content in Branch1 is available in Workspace1.
What should you do?
A. From Workspace1, select Source control, and then select Sync.
B. From Workspace1, select Source control, select Current branch, select Branch1, and then select Commit.
C. From Azure DevOps, merge the contents of the main branch into Branch1.
D. From Workspace1, select Source control, and then select Branch out to new workspace.
Show Answer
Correct Answer: B
Explanation: Select Branch1 as Workspace1’s current branch so the workspace uses that branch’s content. Sync alone applies to the branch already connected to the workspace; branching out creates a different workspace.
Sources:
https://learn.microsoft.com/en-us/fabric/cicd/git-integration/manage-branches
https://learn.microsoft.com/en-us/power-bi/developer/projects/projects-build-pipelines
Question 8
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
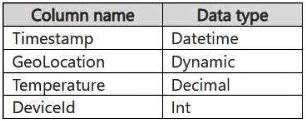
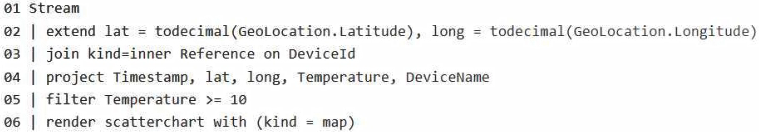
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
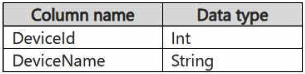
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
You need to reduce how long it takes to run the KQL queryset.
Solution: You add the make_list() function to the output columns.
Does this meet the goal?
A. Yes
B. No
Show Answer
Correct Answer: B
Explanation: No. `make_list()` aggregates values into arrays and adds processing and memory overhead. It does not inherently make the join or filtering faster, and can be costly with millions of rows.
Question 8
You have a Fabric workspace that contains a data pipeline named Pipeline1 and a notebook named Notebook1. Pipeline1 contains an activity that is used to run Notebook1. Pipeline1 is scheduled to run every 10 minutes.
You receive an alert that Pipeline1 failed during the notebook execution activity.
You need to identify in which cell the failure occurred.
What should you do from Monitor in the Fabric admin center?
A. Select the entry for the notebook execution, and then select the logs.
B. Select the entry for the notebook execution, and then view the item snapshot.
C. Select the entry for the pipeline execution, and then view the activity run.
D. Select the entry for the pipeline execution, and then select the output.
Show Answer
Correct Answer: B
Explanation: View the notebook execution’s item snapshot. It shows the notebook as it ran, including cell-level execution results, so you can identify the failed cell. Pipeline activity details identify the failed activity, not necessarily the cell.
Question 9
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
You need to reduce how long it takes to run the KQL queryset.
Solution: You move the filter to line 02.
Does this meet the goal?
A. Yes
B. No
Show Answer
Correct Answer: A
Explanation: Yes. Moving the Temperature filter before the join reduces the number of Stream rows that must be joined with Reference, improving query performance.
Question 9
You have a Fabric workspace that contains a lakehouse named Lakehouse1, a Dataflow Gen2 named Dataflow1, and a pipeline named Pipeline1. Dataflow1 loads data into Lakehouse1.
You need to ensure that Dataflow1 always performs a full data load into Lakehouse1. The solution must minimize how long it takes to load the data.
What should you do?
A. Change the pipeline templates.
B. For Dataflow1, set Update method to Replace.
C. To Dataflow1, add a data preview.
D. To Pipeline1, add an activity to invoke a SQL script.
Show Answer
Correct Answer: B
Explanation: Setting the Dataflow Gen2 destination Update method to Replace causes the target table in the lakehouse to be fully overwritten on each run, achieving a full load without requiring separate delete or SQL steps. This is more efficient than invoking SQL to truncate and reload, and the other options do not control full-load behavior.
$19
Get all 140 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.