HOTSPOT
-
You have a Fabric workspace.
You plan to deploy two Apache Spark environments that will each contain one of the following notebooks:
• Notebook1: A data ingestion notebook that will run as a scheduled Spark job
• Notebook2: An ad hoc notebook for interactive data analysis that will be used by a team of analysts and data scientists
You need to configure the Spark environments to meet the following requirements:
• For the environment that contains Notebook1, minimize compute costs.
• For the environment that contains Notebook2, support multiple concurrent users.
What should you use for each environment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Show Answer
Correct Answer: Notebook1: A serverless Spark environment
Notebook2: A custom Spark pool that has multiple nodes
Explanation: Serverless Spark avoids maintaining dedicated compute for a scheduled job. A multi-node custom pool provides capacity for concurrent interactive users.
Question 10
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
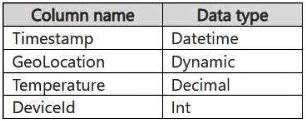
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
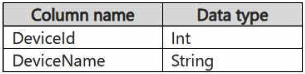
Reference contains reference data in the following format.
Both tables contain millions of rows.
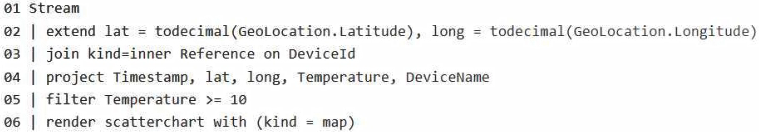
You have the following KQL queryset.
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
A. Yes
B. No
Show Answer
Correct Answer: B
Explanation: No. The query uses an inner join, which returns only matching rows. Changing it to an outer join also retains unmatched rows, so it can require more processing and return more data rather than reduce execution time.
Question 10
HOTSPOT
-
You have a Fabric workspace that contains a large table named Table1. Table1 contains 2 billion rows.
You have a data source that generates a data file every 30 minutes. The file contains only changes that occurred since the last file was generated.
You plan to deploy a data pipeline that will process each data file when it is generated and load the contents into Table1.
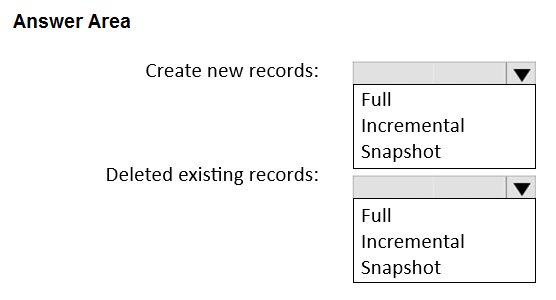
You need to recommend which loading pattern to use for the following operations:
• Create new records.
• Delete existing records.
The solution must support the versioning of existing records.
What should you recommend for each operation? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Show Answer
Correct Answer: Create new records: Incremental
Delete existing records: Snapshot
Explanation: Incremental loading adds new records from each change file without reloading the 2-billion-row table. A snapshot pattern preserves a version of an existing record before its deletion, supporting historical tracking.
Question 11
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
You need to reduce how long it takes to run the KQL queryset.
Solution: You change project to extend.
Does this meet the goal?
A. Yes
B. No
Show Answer
Correct Answer: B
Explanation: No. `project` keeps only the specified columns, reducing the amount of data passed to later operators. Replacing it with `extend` would add or calculate columns while retaining the existing columns, so it would not provide the same column-pruning benefit and may increase the data processed downstream.
Question 11
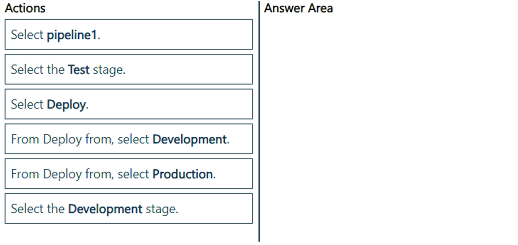
DRAG DROP
-
In the Development workspace, you build a new feature named Feature1.
You need to deploy Feature1 to the Test workspace. The solution must ensure that only a pipeline is deployed.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Show Answer
Correct Answer: 1. Select the Test stage.
2. From Deploy from, select Development.
3. Select pipeline1.
4. Select Deploy.
Explanation: Test is the destination and Development is the source. Selecting only pipeline1 limits the deployment to that item.
Question 11
You have a Fabric workspace named Workspace1 that contains a lakehouse.
You have a Microsoft Entra tenant that contains a user named User1.
You need to ensure that User1 can create items in Workspace1. The solution must follow the principle of least privilege.
Which workspace role should you assign to User1?
A. Member
B. Contributor
C. Admin
D. Viewer
Show Answer
Correct Answer: B
Explanation: In Microsoft Fabric workspace roles, Contributor can create, edit, and delete items in the workspace but cannot manage workspace access or settings. Member has additional permissions beyond item creation, Admin has full control, and Viewer is read-only. Therefore, Contributor satisfies the requirement while following the principle of least privilege.
Question 12
You have two Fabric workspaces named Workspace1 and Workspace2.
You have a Fabric deployment pipeline named deployPipeline1 that deploys items from Workspace1 to Workspace2. DeployPipeline1 contains all the items in Workspace1.
You recently modified the items in Workspaces1.
The workspaces currently contain the items shown in the following table.
Items in Workspace1 that have the same name as items in Workspace2 are currently paired.
You need to ensure that the items in Workspace1 overwrite the corresponding items in Workspace2. The solution must minimize effort.
What should you do?
A. Delete all the items in Workspace2, and then run deployPipeline1.
B. Rename each item in Workspace2 to have the same name as the items in Workspace1.
C. Back up the items in Workspace2, and then run deployPipeline1.
D. Run deployPipeline1 without modifying the items in Workspace2.
Show Answer
Correct Answer: D
Explanation: Run deployPipeline1. Items already paired between the workspaces—such as Model1 and Report1—are updated in Workspace2 with the versions from Workspace1. Deleting or renaming items is unnecessary.
Question 12
You have a Fabric workspace that contains a lakehouse named Lakehouse1.
In an external data source, you have data files that are 500 GB each. A new file is added every day.
You need to ingest the data into Lakehouse1 without applying any transformations. The solution must meet the following requirements:
• Trigger the process when a new file is added.
• Provide the highest throughput.
Which type of item should you use to ingest the data?
A. KQL queryset
B. Streaming dataset
C. Notebook
D. Dataflow Gen2
Show Answer
Correct Answer: C
Explanation: Use a Notebook. Spark can parallelize ingestion across the lakehouse compute resources, making it the best fit for maximizing throughput with 500-GB files. An event-triggered pipeline can start the notebook when a new file arrives. Dataflow Gen2 is less suitable for this very large-volume throughput requirement; the other options are for querying or streaming scenarios.
Question 12
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure key vault named KeyVault1 that contains secrets.
You have a Fabric workspace named Workspace1. Workspace contains a notebook named Notebook1 that performs the following tasks:
• Loads stage data to the target tables in a lakehouse
• Triggers the refresh of a semantic model
You plan to add functionality to Notebook1 that will use the Fabric API to monitor the semantic model refreshes.
You need to retrieve the registered application ID and secret from KeyVault1 to generate the authentication token.
Solution: You use the following code segment:
Use notebookutils.credentials.putSecret and specify the key vault URL and the name of a linked service.
Does this meet the goal?
A. Yes
B. No
Show Answer
Correct Answer: B
Explanation: The goal is to retrieve a secret from Azure Key Vault. notebookutils.credentials.putSecret stores a secret, whereas notebookutils.credentials.getSecret is used to retrieve a secret from a linked Azure Key Vault. Therefore, using putSecret does not meet the requirement.
Question 13
You have a Fabric workspace named Workspace1 that contains the following items:
• A Microsoft Power BI report named Report1
• A Power BI dashboard named Dashboard1
• A semantic model named Model1
• A lakehouse name Lakehouse1
Your company requires that specific governance processes be implemented for the items.
Which items can you endorse in Fabric?
A. Lakehouse1, Model1, and Dashboard1 only
B. Lakehouse1, Model1, Report1 and Dashboard1
C. Report1 and Dashboard1 only
D. Model1, Report1, and Dashboard1 only
E. Lakehouse1, Model1, and Report1 only
Show Answer
Correct Answer: E
Explanation: Lakehouse1, Model1 (the semantic model), and Report1 can be endorsed. Power BI dashboards are not supported for endorsement, so Dashboard1 is excluded.
$19
Get all 140 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.