This is the free Amazon MLA-C01 practice question bank —
120 of 237 total questions, each with a full explanation, free to
read with no signup required. Updated 2026-10-04.
Every answer is verified against official Amazon documentation —
see our methodology.
Question 1
An ML engineer uses A/B testing to dynamically select recommendation models. The models are deployed on Amazon SageMaker AI endpoints. The ML engineer needs to monitor system metrics such as latency, call volume, and HTTP status codes when the endpoints are invoked.
Which solution will meet these requirements with the LEAST operational overhead?
A. Use AWS X-Ray tracing to monitor SageMaker AI endpoints.
B. Configure Amazon CloudWatch dashboards with AWS Lambda log processors.
C. Enable AWS Identity and Access Management (IAM) Access Analyzer to track SageMaker AI endpoint metrics.
D. Deploy AWS Trusted Advisor checks on SageMaker AI endpoint instances.
Show Answer
Correct Answer: B
Explanation: Amazon SageMaker endpoints publish invocation metrics such as latency, invocation count, and error/status metrics natively to Amazon CloudWatch. Using CloudWatch is the managed, low-operational-overhead monitoring solution. While the wording mentions Lambda log processors, the intent is CloudWatch-based monitoring; the other options (X-Ray, IAM Access Analyzer, Trusted Advisor) do not provide native endpoint metric monitoring for these system metrics.
Question 1
HOTSPOT -
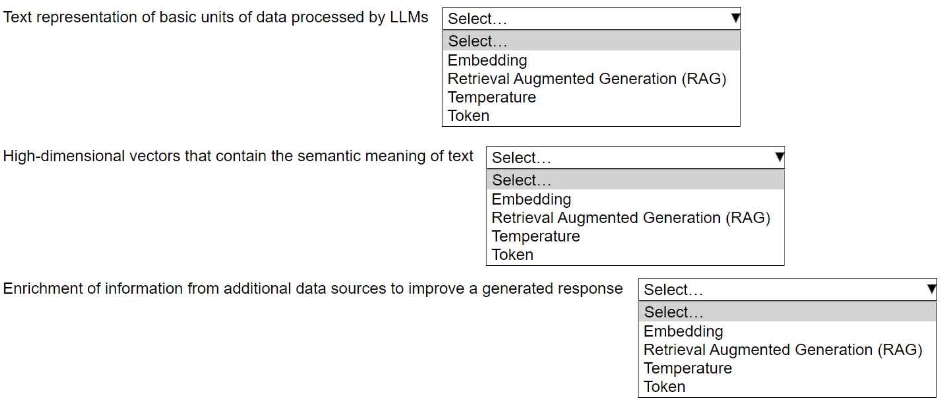
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
• Embedding
• Retrieval Augmented Generation (RAG)
• Temperature
• Token
Explanation: Tokens are the basic units of text processed by LLMs. Embeddings are vectors that encode semantic meaning. RAG retrieves information from additional sources to improve generated responses.
Question 1
HOTSPOT
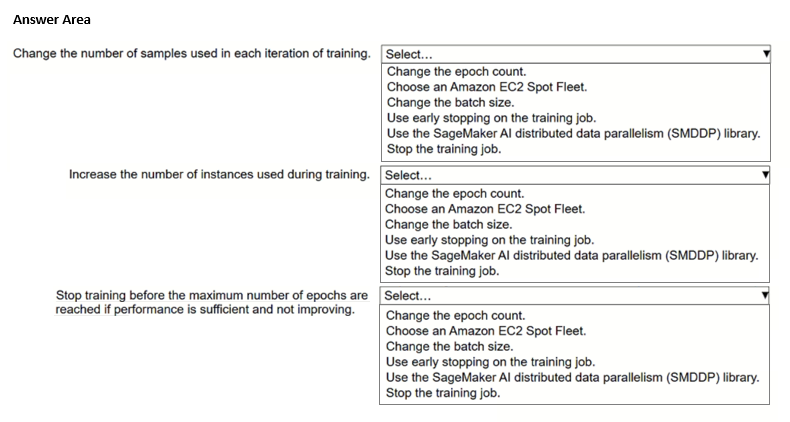
A company uses a training job on Amazon SageMaker AI to train a neural network. The job first trains a model and then evaluates the model's performance against a test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model's final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Choose three.)
• Change the epoch count.
• Choose an Amazon EC2 Spot Fleet.
• Change the batch size.
• Use early stopping on the training job.
• Use the SageMaker AI distributed data parallelism (SMDDP) library.
• Stop the training job.
Show Answer
Correct Answer: 1. Change the batch size.
2. Use the SageMaker AI distributed data parallelism (SMDDP) library.
3. Use early stopping on the training job.
Explanation: Batch size controls samples per iteration. SMDDP distributes training across instances. Early stopping ends training when performance stops improving, avoiding unnecessary epochs.
Question 2
A company is using Amazon SageMaker AI to build an ML model to predict customer behavior. The company needs to explain the bias in the model to an auditor. The explanation must focus on demographics data of the customers.
Which solution will meet these requirements?
A. Use SageMaker Clarify to generate a bias report. Send the report to the auditor.
B. Use AWS Glue DataBrew to create a job to detect drift in the model's data quality. Send the job output to the auditor.
C. Use Amazon Quick Suite (previously known as Amazon QuickSight) integration with SageMaker AI to generate a bias report from Quick Suite. Send the report to the auditor.
D. Use Amazon CloudWatch metrics from the SageMaker AI namespace to create a bias dashboard. Share the dashboard with the auditor.
Show Answer
Correct Answer: A
Explanation: Amazon SageMaker Clarify is designed to detect and explain bias in machine learning datasets and models, including analysis across sensitive demographic attributes. It generates bias reports suitable for auditing. AWS Glue DataBrew focuses on data preparation and quality, not ML bias; Quick Suite does not generate SageMaker bias reports; CloudWatch metrics monitor operational aspects rather than providing bias explanations.
Question 2
HOTSPOT -
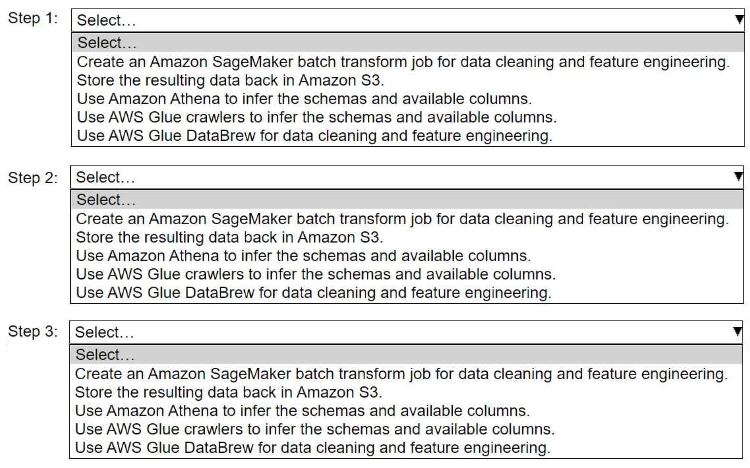
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
• Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
• Store the resulting data back in Amazon S3.
• Use Amazon Athena to infer the schemas and available columns.
• Use AWS Glue crawlers to infer the schemas and available columns.
• Use AWS Glue DataBrew for data cleaning and feature engineering.
Show Answer
Correct Answer: 1. Use AWS Glue crawlers to infer the schemas and available columns.
2. Use AWS Glue DataBrew for data cleaning and feature engineering.
3. Store the resulting data back in Amazon S3.
Explanation: Glue crawlers discover the structure of the unlabeled CSV data. DataBrew cleans missing values and prepares features; S3 stores the prepared dataset for model training.
Question 2
HOTSPOT
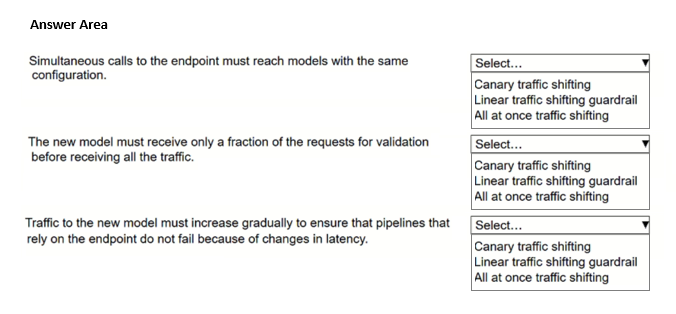
A company has multiple models that are hosted on Amazon SageMaker AI. The models need to be re-trained. The requirements for each model are different, so the company needs to choose different deployment strategies to transfer all requests to a new model.
Select the correct strategy from the following list for each requirement. Select each strategy one time.
• Canary traffic shifting
• Linear traffic shifting guardrail
• All at once traffic shifting
Show Answer
Correct Answer: 1. All at once traffic shifting
2. Canary traffic shifting
3. Linear traffic shifting guardrail
Explanation: All at once switches every request together. Canary sends a small fraction to the new model before switching the rest. Linear shifting increases the new model’s traffic gradually so latency can be monitored.
Question 3
A company wants to launch a new website feature that predicts home prices based on user-supplied home attributes. The attributes include location, square footage, and number of bedrooms and bathrooms.
An ML engineer has trained a regression model by using the Amazon SageMaker AI XGBoost algorithm. The model performs well with training data. However, the model significantly underperforms when it is validated against real-world data.
Which solution will improve the model’s validation score with the LEAST implementation effort?
A. Create a larger training dataset that includes more real-world data. Retrain the model.
B. Increase the value of the num_round hyperparameter.
C. Change the eval_metric hyperparameter from Root Mean Square Error (RMSE) to Error.
D. Increase the value of the lambda hyperparameter.
Show Answer
Correct Answer: D
Explanation: Strong training performance but poor real-world validation performance indicates overfitting. Increasing XGBoost’s `lambda` adds L2 regularization, which can reduce overfitting with only a hyperparameter change. More representative training data could also help, but requires collecting and preparing additional data; changing the evaluation metric does not improve the model, and increasing `num_round` can worsen overfitting.
Question 3
An ML engineering team is spread across multiple locations. When the lead ML engineer opens an Amazon SageMaker Al notebook, the ML engineer does not see the latest merged notebook made by other team members from a Git repository.
The lead ML engineer must see the latest SageMaker AI notebook updates.
Which solution will meet this requirement?
A. Run the !git pull origin master command.
B. Run the !git commit command.
C. Run the !git push origin master command.
D. Run the !git branch command.
Show Answer
Correct Answer: A
Explanation: To update the local notebook repository with the latest merged changes from the remote Git repository, the engineer should run `git pull origin master`. This fetches the latest commits from the remote `master` branch and merges them into the local branch. `git commit` only records local changes, `git push` uploads local commits to the remote, and `git branch` only lists or manages branches.
Question 3
HOTSPOT -
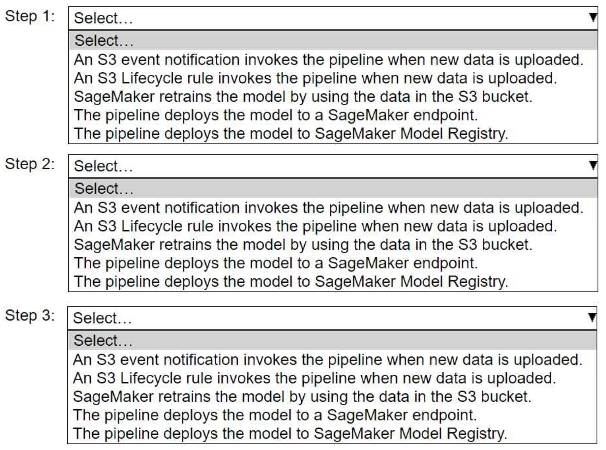
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline's correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
• An S3 event notification invokes the pipeline when new data is uploaded.
• S3 Lifecycle rule invokes the pipeline when new data is uploaded.
• SageMaker retrains the model by using the data in the S3 bucket.
• The pipeline deploys the model to a SageMaker endpoint.
• The pipeline deploys the model to SageMaker Model Registry.
Show Answer
Correct Answer: 1. An S3 event notification invokes the pipeline when new data is uploaded.
2. SageMaker retrains the model by using the data in the S3 bucket.
3. The pipeline deploys the model to a SageMaker endpoint.
Explanation: The upload triggers the pipeline, which retrains the model and then deploys it for inference. Model Registry stores model versions; it does not host the model.
Question 4
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company’s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
A. Create a new LLM on Amazon Bedrock. Train the new LLM on the original dataset and the company documentation. Make the new model available in Bedrock for calls from the chat interface.
B. Integrate the company documentation with Amazon Bedrock guardrails. Invoke the guardrails for all Amazon Bedrock calls from the chat interface.
C. Use all the text files to fine tune a model in Amazon Bedrock. Use the fine-tuned model to process user prompts.
D. Upload all the text files to an Amazon Bedrock knowledge base. Use the knowledge base to provide context when the chat interface makes calls to Amazon Bedrock.
Show Answer
Correct Answer: D
Explanation: Amazon Bedrock Knowledge Bases implement a retrieval-augmented generation (RAG) pattern by indexing the company's documents and retrieving relevant content at query time. This is ideal for documentation that changes frequently because updates only require refreshing the knowledge base rather than retraining or fine-tuning a model. Creating or training a new model is unnecessary and expensive, fine-tuning is not appropriate for frequently changing reference documents, and guardrails are for safety and policy enforcement, not knowledge injection.
$19
Get all 237 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.