An ML engineer is tuning an image classification model that shows poor performance on one of two available classes during prediction. Analysis reveals that the images whose class the model performed poorly on represent an extremely small fraction of the whole training dataset.
The ML engineer must improve the model’s performance.
Which solution will meet this requirement?
A. Optimize for accuracy. Use image augmentation on the less common images to generate new samples.
B. Optimize for F1 score. Use image augmentation on the less common images to generate new samples.
C. Optimize for accuracy. Use Synthetic Minority Oversampling Technique (SMOTE) on the less common images to generate new samples.
D. Optimize for F1 score. Use Synthetic Minority Oversampling Technique (SMOTE) on the less common images to generate new samples.
Show Answer
Correct Answer: B
Explanation: With a severely underrepresented class, accuracy can remain high while minority-class performance is poor. Optimizing F1 better balances precision and recall, and image augmentation can create varied training examples from the minority-class images. SMOTE is generally intended for tabular feature vectors rather than raw images.
Question 4
A company is planning to use Amazon SageMaker to make classification ratings that are based on images. The company has 6 ТВ of training data that is stored on an Amazon FSx for NetApp ONTAP system virtual machine (SVM). The SVM is in the same VPC as SageMaker.
An ML engineer must make the training data accessible for ML models that are in the SageMaker environment.
Which solution will meet these requirements?
A. Mount the FSx for ONTAP file system as a volume to the SageMaker Instance.
B. Create an Amazon S3 bucket. Use Mountpoint for Amazon S3 to link the S3 bucket to the FSx for ONTAP file system.
C. Create a catalog connection from SageMaker Data Wrangler to the FSx for ONTAP file system.
D. Create a direct connection from SageMaker Data Wrangler to the FSx for ONTAP file system.
Show Answer
Correct Answer: A
Explanation: Mounting the FSx for NetApp ONTAP file system makes the image data accessible from the SageMaker instance in the same VPC. Data Wrangler does not provide the proposed direct or catalog connection to FSx for ONTAP, and Mountpoint for Amazon S3 does not link an S3 bucket to that file system. For a separate managed training job, the mount must also be configured in its training environment; ONTAP is not a native SageMaker training input channel.
Sources:
https://aws.amazon.com/blogs/architecture/designing-a-hybrid-ai-ml-data-access-strategy-with-amazon-sagemaker
https://aws.amazon.com/blogs/machine-learning/use-snowflake-as-a-data-source-to-train-ml-models-with-amazon-sagemaker
Question 5
A company is performing A/B testing on a model that provides product recommendations. The company has deployed two versions of the model and is showing each version of the model to 50% of users randomly.
Which metric should the company use to evaluate whether users act on a recommendation?
A. The conversion rates between the two versions of the model
B. The number of recommendations provided to each user
C. The model accuracy on held-out test data
D. The latency of model inference
Show Answer
Correct Answer: A
Explanation: In an A/B test for recommendation systems, the key outcome is whether users take the desired action after receiving recommendations. Conversion rate directly measures user response (such as clicking, purchasing, or otherwise acting on recommendations) and is the appropriate metric for comparing the two model versions. Recommendation count, offline accuracy, and inference latency do not directly measure user adoption of recommendations.
Question 5
HOTSPOT
-
A company is using Amazon SageMaker to deploy a new version of its ML model.
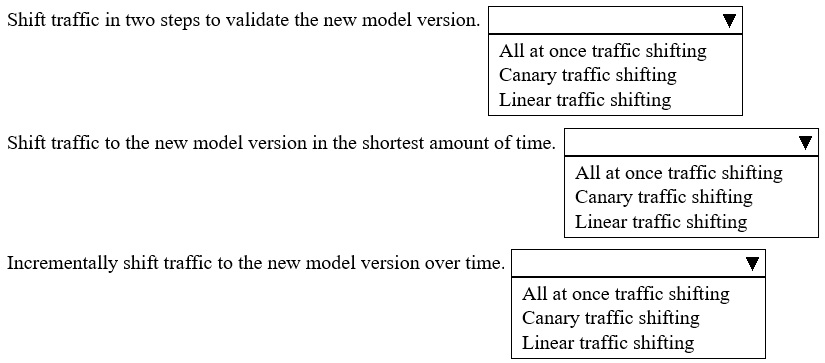
Select the correct SageMaker traffic shifting strategy from the following list for each use case. Each traffic shifting strategy should be selected one time. (Choose three.)
• All at once traffic shifting
• Canary traffic shifting
• Linear traffic shifting
Show Answer
Correct Answer: 1. Canary traffic shifting
2. All at once traffic shifting
3. Linear traffic shifting
Explanation: Canary shifts traffic in two steps; all at once is fastest; linear shifts traffic incrementally over time.
Question 5
Case study -
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The ML engineer needs to use an Amazon SageMaker built-in algorithm to train the model.
Which algorithm should the ML engineer use to meet this requirement?
A. LightGBM
B. Linear learner
C. К-means clustering
D. Neural Topic Model (NTM)
Show Answer
Correct Answer: A
Explanation: LightGBM is suited to this supervised fraud-detection task: its boosted decision trees can capture nonlinear feature interactions and complex patterns, and it supports handling class imbalance. Linear Learner is less suited to complex interdependencies because it learns a linear decision function; K-means and NTM are not appropriate for this classification requirement.
Question 6
A company uses an ML model to recommend videos to users. The model is deployed on Amazon SageMaker AI. The model performed well initially after deployment, but the model’s performance has degraded over time.
Which solution can the company use to identify model drift in the future?
A. Create a monitoring job in SageMaker Model Monitor. Then create a baseline from the training dataset.
B. Create a baseline from the training dataset. Then create a monitoring job in SageMaker Model Monitor.
C. Create a baseline by using a built-in rule in SageMaker Clarify. Monitor the drift in Amazon CloudWatch.
D. Retrain the model on new data. Compare the retrained model's performance to the original model’s performance.
Show Answer
Correct Answer: B
Explanation: Amazon SageMaker Model Monitor detects data and model quality drift by first creating a baseline from the training dataset (capturing expected statistics and constraints), then running a monitoring job that compares production inference data against that baseline. This is the standard workflow for ongoing drift detection.
Question 6
An airline company uses an ML model to adjust ticket prices based on demand. The model runs on Amazon SageMaker real-time endpoints. During previous deployments, the model failed to scale quickly enough when website traffic increased, which caused delays in price adjustments.
An ML engineer needs to configure auto scaling for the SageMaker endpoints to respond rapidly to traffic changes. The solution must use target tracking scaling policies.
Which configuration will be MOST responsive to sudden changes in traffic?
A. Configure auto scaling based on the SageMaker AI InvocationsPerInstance standard metric. Configure 10-second interval resolution, and set the default 300-second scale-in cooldown period.
B. Configure auto scaling based on the SageMaker AI InvocationsPerInstance metric. Configure high-resolution 10-second intervals, and set a 600-second scale-in cooldown period.
C. Configure auto scaling based on the SageMaker InvocationsPerInstance standard metric. Configure 10-second intervals resolution, and set a 600-second scale-in cooldown period.
D. Configure auto scaling based on the SageMaker InvocationsPerInstance metric. Configure high-resolution 10-second intervals, and set the default 300-second scale-in cooldown period.
Show Answer
Correct Answer: D
Explanation: Use the InvocationsPerInstance metric with high-resolution 10-second intervals so scaling can react to traffic changes more quickly. The default 300-second scale-in cooldown is more responsive than a 600-second cooldown.
Question 6
An ML engineer receives datasets that contain missing values, duplicates, and extreme outliers. The ML engineer must consolidate these datasets into a single data frame and must prepare the data for ML.
Which solution will meet these requirements?
A. Use Amazon SageMaker Data Wrangler to import the datasets and to consolidate them into a single data frame. Use the cleansing and enrichment functionalities to prepare the data.
B. Use Amazon SageMaker Ground Truth to import the datasets and to consolidate them into a single data frame. Use the human-in-the-loop capability to prepare the data.
C. Manually import and merge the datasets. Consolidate the datasets into a single data frame. Use Amazon Q Developer to generate code snippets that will prepare the data.
D. Manually import and merge the datasets. Consolidate the datasets into a single data frame. Use Amazon SageMaker data labeling to prepare the data.
Show Answer
Correct Answer: A
Explanation: Amazon SageMaker Data Wrangler can import and combine datasets in a data flow and provides built-in transformations for handling missing values, duplicates, and outliers to prepare data for machine learning. Ground Truth and data labeling focus on labeling data, not cleaning it.
Question 7
An ML engineer used Amazon SageMaker Studio to train a neural network. The neural network logs its information into TensorBoard and uses stochastic gradient descent (SGD) as the optimizer.
The ML engineer reviewed training graphs and discovered that the accuracy was not increasing and the loss was decreasing very slowly. The ML engineer needs to improve the model’s performance without increasing the total training time.
Which solution will meet these requirements?
A. Increase the initial learning rate.
B. Decrease the initial learning rate.
C. Increase the total number of epochs.
D. Decrease the total number of epochs.
Show Answer
Correct Answer: A
Explanation: If loss is decreasing very slowly and accuracy is not improving, the SGD optimizer is likely making updates that are too small due to a learning rate that is too low. Increasing the initial learning rate can accelerate convergence without increasing total training time. Decreasing the learning rate would slow training further, increasing epochs would increase training time, and decreasing epochs would likely worsen performance.
Question 7
HOTSPOT
-
An ML engineer needs to use Amazon SageMaker to develop an ML solution for a company. The solution will use streaming video from cameras to count the number of people who walk past the company’s store every day.
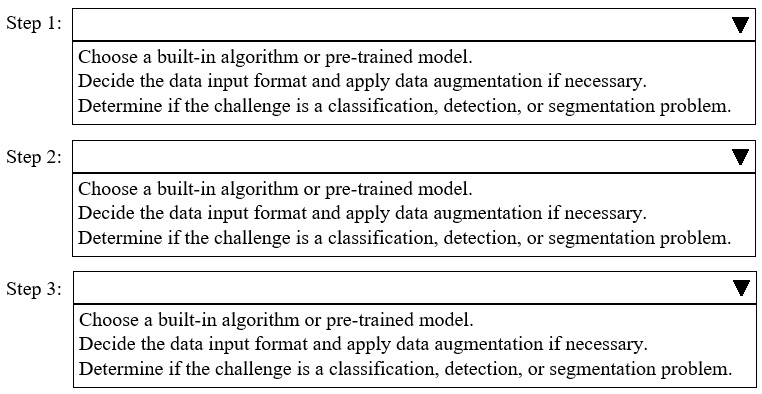
Select and order the steps from the following list to implement the first version of the algorithm. Each step should be selected one time. (Select and order three.)
• Choose a built-in algorithm or pre-trained model.
• Decide the data input format and apply data augmentation if necessary.
• Determine if the challenge is a classification, detection, or segmentation problem.
Show Answer
Correct Answer: Step 1: Determine if the challenge is a classification, detection, or segmentation problem.
Step 2: Choose a built-in algorithm or pre-trained model.
Step 3: Decide the data input format and apply data augmentation if necessary.
Explanation: Counting people in video frames requires detecting people. After selecting a suitable detection model, prepare its required input format and augment the data if needed.
$19
Get all 237 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.