A medical company ingests streams of data from devices that monitor patients’ vital signs. The company uses Amazon SageMaker and plans to prepare ML models to predict adverse events for patients. The dataset is large with thousands of features.
An ML engineer needs to run several hundred training iterations with different sets of features, different algorithms, and many potential parameters. The ML engineer must implement a solution to log the characteristics and results of each training iteration.
Which solution will meet these requirements with the LEAST implementation effort?
A. Use Amazon CloudWatch to create custom metrics for the characteristics of each iteration.
B. Write the characteristics of each iteration to logs in Amazon S3. Use AWS Glue and Amazon Athena to search the logs.
C. Use the SageMaker Model Registry to track the characteristics and results of each iteration.
D. Use SageMaker Experiments to track the characteristics and results of each iteration.
Show Answer
Correct Answer: D
Explanation: SageMaker Experiments is designed to organize and track ML experiments, including training runs, hyperparameters, feature sets, algorithms, input artifacts, and evaluation metrics. It enables comparison across hundreds of iterations with minimal implementation effort. CloudWatch is for monitoring metrics, S3/Glue/Athena requires custom logging and querying, and Model Registry is intended for managing and versioning models after training rather than tracking experiment iterations.
Question 95
A company is training a large language model (LLM) by using on-premises infrastructure. A live conversational engine uses the LLM to help customers find real-time insights in credit card data.
An ML engineer must implement a solution to train and deploy the LLM on Amazon SageMaker.
Which solution will meet these requirements?
A. Use SageMaker Training Compiler to train the LLM. Deploy the LLM by using SageMaker real-time inference.
B. Use SageMaker with deep learning containers for large model inference to train the LLM. Deploy the LLM by using SageMaker real-time inference.
C. Use SageMaker Notebook Jobs to train the LLM. Deploy the LLM by using SageMaker Asynchronous Inference.
D. Use SageMaker Studio to train the LLM. Deploy the LLM by using SageMaker batch transform.
Show Answer
Correct Answer: A
Explanation: SageMaker Training Compiler is designed to optimize and accelerate training of deep learning models, including supported transformer workloads, while SageMaker real-time inference is the appropriate deployment option for a live conversational application that requires low-latency responses. The Large Model Inference (LMI) containers are intended for inference hosting rather than training. Notebook Jobs and Studio are development/orchestration environments, not the primary training mechanism, and asynchronous inference or batch transform do not fit a real-time conversational workload.
Sources:
https://officialdumps.com/exam/mla-c01
Question 96
A company has several teams that have developed separate prediction models on their own laptops. The teams developed the models by using Python with scikit-learn and TensorFlow frameworks.
The company must rebuild the models and must integrate the models into an ML infrastructure that the company manages by using Amazon SageMaker. The company also must incorporate the models into a model registry.
Which solution will meet these requirements with the LEAST operational overhead?
A. Export the models from the laptops to an Amazon S3 bucket. Use an Amazon API Gateway REST API and AWS Lambda functions with SageMaker endpoints to access the models. Register the models in the SageMaker Model Registry.
B. Import the models into the SageMaker Model Registry. Use SageMaker to run the imported models.
C. Use code from the laptops to create containers for the models. Use the bring your own container (BYOC) functionality of SageMaker to import and use the models. Register the models in the SageMaker Model Registry.
D. Import the Python-based models into SageMaker. Rebuild the scikit-learn and TensorFlow models in SageMaker. Register all the models in the SageMaker Model Registry.
Show Answer
Correct Answer: D
Explanation: SageMaker provides built-in training and inference containers for scikit-learn and TensorFlow, so the models can be rebuilt in a managed SageMaker environment without maintaining custom containers. After training, the models can be registered directly in SageMaker Model Registry. Using BYOC adds container management overhead, and simply importing arbitrary locally trained models into the registry is not a supported generic workflow for rebuilding and managing them in SageMaker. API Gateway and Lambda are unrelated to the requirement to rebuild and register the models.
Question 97
HOTSPOT
-
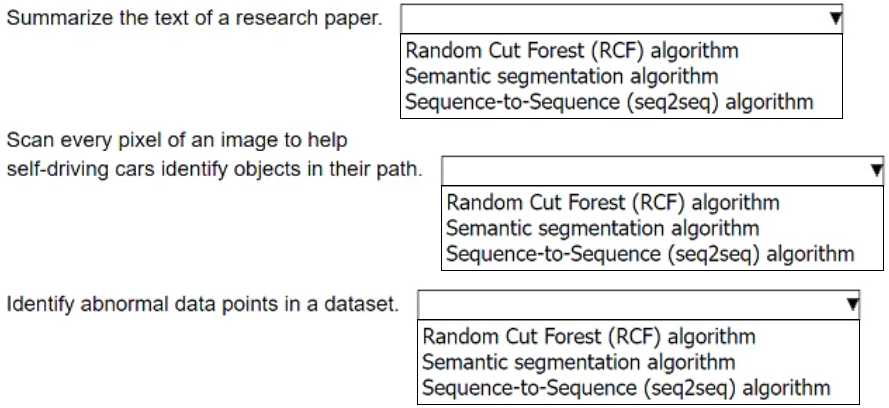
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
• Random Cut Forest (RCF) algorithm
• Semantic segmentation algorithm
• Sequence-to-Sequence (seq2seq) algorithm
Show Answer
Correct Answer: Summarize research paper → Sequence-to-Sequence (seq2seq) algorithm
Scan every pixel for self-driving object identification → Semantic segmentation algorithm
Identify abnormal data points → Random Cut Forest (RCF) algorithm
Explanation: Seq2Seq is used for text generation tasks such as summarization. Semantic segmentation classifies each image pixel. Random Cut Forest is used for anomaly detection.
Question 98
An ML engineer wants to use a set of survey responses as training data for an ML classifier. All the survey responses are either “yes” or “no.”
The ML engineer needs to convert the responses into a feature that will produce better model training results. The ML engineer must not increase the dimensionality of the dataset.
Which methods will meet these requirements? (Choose two.)
A. Binary encoding
B. Label encoding
C. One-hot encoding
D. Statistical imputation
E. Tokenization
Show Answer
Correct Answer: A, B
Explanation: For a binary categorical feature with values 'yes' and 'no', label encoding maps the categories to a single numeric column (for example, yes=1, no=0) without increasing dimensionality. Binary encoding also represents categorical values using binary digits and, for a two-category feature, does not increase the number of dimensions in practice. One-hot encoding adds columns, statistical imputation is for missing values, and tokenization is for splitting text rather than encoding a binary categorical feature.
Question 100
A company is developing a new ML model that uses the XGBoost algorithm. The company will train the model on data that is stored in an Amazon S3 bucket. The data is in a nested JSON format.
An ML engineer needs to convert the JSON files into a tabular format.
Which solution will meet this requirement with the LEAST operational overhead?
A. Create an AWS Glue PySpark job that uses the Relationalize transform to convert the files.
B. Write custom Scala code to convert the files. Use Amazon EMR Serverless to run the Scala code.
C. Create an AWS Lambda function that uses a Python runtime and invokes the reduce() function to convert the files. Invoke the Lambda function.
D. Create an Amazon Athena database that is based on the JSON files. Use the Athena flatten function to convert the data.
Show Answer
Correct Answer: A
Explanation: AWS Glue provides a managed ETL service with a built-in Relationalize transform specifically designed to flatten nested JSON into tabular structures. This minimizes custom code and operational overhead compared to managing EMR jobs, implementing custom Lambda transformations, or relying on Athena, which is primarily a query service and not intended for transforming datasets into tabular training data.
Question 101
A company is building an ML model by using Amazon SageMaker, AWS owned libraries, and open source libraries. The company must ensure that SageMaker does not collect metadata about usage and errors during training.
Which solution will meet these requirements?
A. Associate the SageMaker domain with a custom IAM role. Attach the role to a policy that denies Amazon CloudWatch service usage logs.
B. Add an IAM role to the SageMaker domain to deny Amazon CloudWatch the permission to report metadata.
C. Turn off the setting in the SageMaker domain to share metadata for console jobs. Opt out of metadata collection for each training job that is submitted through the AWS CLI or AWS SDKs.
D. Set a parameter to opt out of metadata collection for each training job that is submitted through the AWS CLI, Boto3, or the SageMaker Python SDK.
Show Answer
Correct Answer: D
Explanation: Amazon SageMaker provides an opt-out parameter for metadata collection on training jobs submitted through supported SDKs and the AWS CLI. IAM policies denying CloudWatch access do not disable SageMaker's metadata collection, and the console sharing setting applies to console jobs rather than all programmatic training jobs. Therefore, setting the opt-out parameter for each training job is the required solution.
Question 103
An ML engineer needs to deploy a trained model that is based on a genetic algorithm. The algorithm solves a complex problem and can take several minutes to generate predictions.
When the model is deployed, the model needs to access large amounts of data to process requests. The requests can involve as much as 100 MB of data.
Which deployment solution will meet these requirements with the LEAST operational overhead?
A. Deploy the model to Amazon EC2 instances in an Auto Scaling group behind an Application Load Balancer.
B. Deploy the model to an Amazon SageMaker real-time endpoint.
C. Deploy the model to an Amazon SageMaker Asynchronous Inference endpoint.
D. Package the model as a container. Deploy the model to Amazon Elastic Container Service (Amazon ECS) on Amazon EC2 instances.
Show Answer
Correct Answer: C
Explanation: Amazon SageMaker Asynchronous Inference is designed for inference requests that can take minutes to complete and supports large payloads (up to hundreds of MB). It queues requests, processes them asynchronously, and stores responses in Amazon S3, minimizing operational overhead compared with managing EC2 or ECS infrastructure. SageMaker real-time endpoints are intended for low-latency inference, while EC2/ECS deployments require more infrastructure management.
Question 104
A company has an existing Amazon SageMaker model (v1) on a production endpoint. The company develops a new model version (v2) and needs to test v2 in production before substituting v2 for v1.
The company needs to implement a solution to minimize the risk of v2 generating incorrect output in production. The solution must prevent any disruption of production traffic during the change to v2.
Which solution will meet these requirements?
A. Create a second production variant for v2. Assign 1% of the traffic to v2 and 99% of the traffic to v1. Collect all the output of v2 in an Amazon S3 bucket. If v2 performs as expected, switch all the traffic to v2.
B. Create a second production variant for v2. Assign 10% of the traffic to v2 and 90% of the traffic to v1. Collect all the output of v2 in an Amazon S3 bucket. If v2 performs as expected, switch all the traffic to v2.
C. Deploy v2 to a new endpoint. Turn on data capturing for the production endpoint. Write a script to pass 100% of input data to v2. If v2 performs as expected, deactivate the v1 endpoint and direct the traffic to v2.
D. Deploy v2 into a shadow variant that samples 100% of the inference requests. Collect all the output in an Amazon S3 bucket. If v2 performs as expected, promote v2 to production.
Show Answer
Correct Answer: D
Explanation: Shadow variants in Amazon SageMaker allow a new model version to receive a copy of production inference requests without affecting live responses. Production traffic continues to be served by v1, eliminating disruption while collecting v2 outputs for evaluation. After validation, the shadow model can be promoted to production. Canary traffic splitting (1% or 10%) exposes some real users to v2 responses, and deploying to a separate endpoint with custom duplication is more complex and does not match the built-in zero-impact shadow testing capability.
Question 105
A company runs an ML model on Amazon SageMaker. The company uses an automatic process that makes API calls to create training jobs for the model. The company has new compliance rules that prohibit the collection of aggregated metadata from training jobs.
Which solution will prevent SageMaker from collecting metadata from the training jobs?
A. Opt out of metadata tracking for any training job that is submitted.
B. Ensure that training jobs are running in a private subnet in a custom VPC.
C. Encrypt the training data with an AWS Key Management Service (AWS KMS) customer managed key.
D. Reconfigure the training jobs to use only AWS Nitro instances.
Show Answer
Correct Answer: A
Explanation: Amazon SageMaker allows customers to opt out of collecting and storing aggregated training job metadata for submitted training jobs. The other options (private VPC, KMS encryption, or Nitro instances) improve networking, encryption, or infrastructure security but do not disable SageMaker's metadata collection.
$19
Get all 237 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.