A company deployed an Amazon SageMaker AI ML model to an endpoint by calling the CreateModel API operation. The network that was established with the API call includes two private subnets and one security group.
The model must download data from an Amazon S3 bucket and must upload data to the S3 bucket. The traffic to the S3 bucket must not travel across the internet.
Which solution will meet these requirements?
A. Create a NAT gateway. Configure the security group to allow outbound connections. Configure route tables to redirect any traffic to the S3 bucket through the NAT gateway.
B. Create a gateway VPC endpoint. Configure an endpoint policy that restricts access to the S3 bucket. Configure route tables to redirect any traffic to the S3 bucket through the endpoint.
C. Create an interface VPC endpoint. Verify that the security group allows only inbound connections. Configure route tables to redirect any traffic to the S3 bucket through the endpoint.
D. Create a Gateway Load Balancer VPC endpoint. Configure an IAM policy that restricts access to the S3 bucket. Configure route tables to redirect any traffic to the S3 bucket through the endpoint.
Show Answer
Correct Answer: B
Explanation: Amazon S3 uses a gateway VPC endpoint (not an interface endpoint in the standard exam context) to keep traffic between resources in a VPC and S3 on the AWS network without traversing the internet. The route tables for the private subnets must include the gateway endpoint route, and an endpoint policy can restrict access to the required S3 bucket. A NAT gateway sends traffic out for internet access, and a Gateway Load Balancer endpoint is unrelated to S3 access.
Question 63
A company is developing an ML model by using Amazon SageMaker AI. The company must monitor bias in the model and must display the results on a dashboard. An ML engineer creates a bias monitoring job.
How should the ML engineer capture bias metrics to display on the dashboard?
A. Capture AWS CloudTrail metrics from SageMaker Clarify.
B. Capture Amazon CloudWatch metrics from SageMaker Clarify.
C. Capture SageMaker Model Monitor metrics from Amazon EventBridge.
D. Capture SageMaker Model Monitor metrics from Amazon Simple Notification Service (Amazon SNS).
Show Answer
Correct Answer: B
Explanation: Amazon SageMaker Clarify is used to detect and monitor bias. Clarify publishes bias metrics to Amazon CloudWatch, where they can be visualized on CloudWatch dashboards. CloudTrail records API activity rather than model bias metrics, and EventBridge or SNS are not the primary mechanisms for capturing and displaying Clarify bias metrics.
Question 64
A company is using an ML model to classify motion in videos. The data is stored in MP4 format in Amazon S3. When the company created the model, the company needed 4 months to label all the video frames.
The company needs to retrain the model with an existing training workflow in Amazon SageMaker AI. An ML engineer must implement a solution that decreases the labeling time.
Which solution will meet these requirements?
A. Use SageMaker Ground Truth to annotate the video frames.
B. Use SageMaker JumpStart to use pre-trained computer vision models to develop a labeling model.
C. Use SageMaker Data Wrangler to create a data workflow. Use the workflow to optimize the labeling process.
D. Use the labeling interface of Amazon Augmented AI (Amazon A2I) with Amazon Rekognition to label the video frames.
Show Answer
Correct Answer: A
Explanation: Amazon SageMaker Ground Truth is the AWS service designed for large-scale data labeling, including video frame annotation. It includes built-in video labeling workflows and automated data labeling (active learning) to reduce the amount of manual labeling required, making it well suited to shorten retraining dataset preparation. SageMaker JumpStart provides pretrained models rather than a labeling workflow, Data Wrangler is for data preparation, and Amazon A2I is for human review of ML predictions rather than a primary video labeling solution.
Question 65
An ML engineer is setting up an Amazon SageMaker AI pipeline for an ML model. The pipeline must automatically initiate a re-training job if any data drift is detected.
How should the ML engineer set up the pipeline to meet this requirement?
A. Use an AWS Glue crawler and an AWS Glue extract, transform and load (ETL) job to detect data drift. Use AWS Glue triggers to automate the re-training job.
B. Use Amazon Managed Service for Apache Flink to detect data drift. Use an AWS Lambda function to automate the re-training job.
C. Use SageMaker Model Monitor to detect data drift. Use an AWS Lambda function to automate the re-training job.
D. Use Amazon QuickSight anomaly detection to detect data drift. Use an AWS Step Functions workflow to automate the re-training job.
Show Answer
Correct Answer: C
Explanation: SageMaker Model Monitor is the AWS service designed to detect data drift and model quality issues for SageMaker deployments. When drift is detected, it can emit Amazon CloudWatch metrics/alarms that trigger an AWS Lambda function to start a SageMaker retraining pipeline or training job. The other options use services not intended for ML data drift detection.
Question 66
A company is developing a new ML model to rank customers in order of their potential to pay back loans. The company needs to use an Amazon SageMaker AI built-in algorithm.
Which algorithm should the company use to meet these requirements?
A. XGBoost
B. K-means clustering
C. Principal component analysis (PCA)
D. Neural Topic Model (NTM)
Show Answer
Correct Answer: A
Explanation: XGBoost is a supervised learning algorithm suitable for predicting loan repayment likelihood from structured tabular data. Its prediction scores can be used to rank customers by probability of repayment. K-means is for unsupervised clustering, PCA is for dimensionality reduction, and NTM is for topic modeling of text.
Question 67
An ML engineer is analyzing a classification dataset before training a model in Amazon SageMarker AI. The ML engineer suspects that the dataset has a significant imbalance between class labels that could lead to biased model predictions. To confirm class imbalance, the ML engineer needs to select an appropriate pre-training bias metric.
Which metric will meet this requirement?
A. Mean square error (MSE)
B. Difference in proportions of labels (DPL)
C. Silhouette score
D. Structural similarity index measure (SSIM)
Show Answer
Correct Answer: B
Explanation: Difference in proportions of labels (DPL) is an Amazon SageMaker Clarify pre-training bias metric that measures imbalance in the distribution of class labels between facets or groups. It is appropriate for confirming label imbalance before training. MSE is a regression error metric, Silhouette score evaluates clustering quality, and SSIM measures image similarity.
Question 68
A company needs to deploy a custom-trained classification ML model on AWS. The model must make near real-time predictions with low latency and must handle variable request volumes.
Which solution will meet these requirements?
A. Create an Amazon SageMaker AI batch transform job to process inference requests in batches.
B. Use Amazon API Gateway to receive prediction requests. Use an Amazon S3 bucket to host and serve the model.
C. Deploy an Amazon SageMaker AI endpoint. Configure auto scaling for the endpoint.
D. Launch AWS Deep Learning AMIs (DLAMI) on two Amazon EC2 instances. Run the instances behind an Application Load Balancer.
Show Answer
Correct Answer: C
Explanation: Amazon SageMaker real-time inference endpoints are designed for low-latency, near real-time predictions. Configuring endpoint auto scaling allows the service to automatically adjust capacity to handle variable request volumes. Batch transform is for offline batch inference, S3 cannot directly host a model for inference behind API Gateway, and managing DLAMI instances behind an ALB is more operationally complex and not the managed service best suited for this requirement.
Question 69
An ML engineer is collecting data to train a classification ML model by using Amazon SageMaker AI. The target column can have two possible values: Class A or Class B. The ML engineer wants to ensure that the number of samples for both Class A and Class B are balanced, without losing any existing training data. The ML engineer must test the balance of the training data.
Which solution will meet this requirement?
A. Use SageMaker Clarify to check for class imbalance (CI). If the value is equal to 0, then use random undersampling in SageMaker Data Wrangler to balance the classes.
B. Use SageMaker Clarify to check for class imbalance (CI). If the value is greater than 0, then use synthetic minority oversampling technique (SMOTE) in SageMaker Data Wrangler to balance the classes.
C. Use SageMaker JumpStart to generate a class imbalance (CI) report. If the value is greater than 0, then use random undersampling in SageMaker Studio to balance the classes.
D. Use SageMaker JumpStart to generate a class imbalance (CI) report. If the value is equal to 0, then use synthetic minority oversampling technique (SMOTE) in SageMaker Studio to balance the classes.
Show Answer
Correct Answer: B
Explanation: SageMaker Clarify provides class imbalance (CI) analysis for datasets. A CI value greater than 0 indicates imbalance. Because the requirement is to balance the classes without losing any existing training data, SMOTE in SageMaker Data Wrangler is appropriate since it oversamples the minority class by generating synthetic examples rather than removing majority-class samples. Random undersampling would discard existing data, and JumpStart is not the service used for CI reporting.
Question 71
HOTSPOT
-
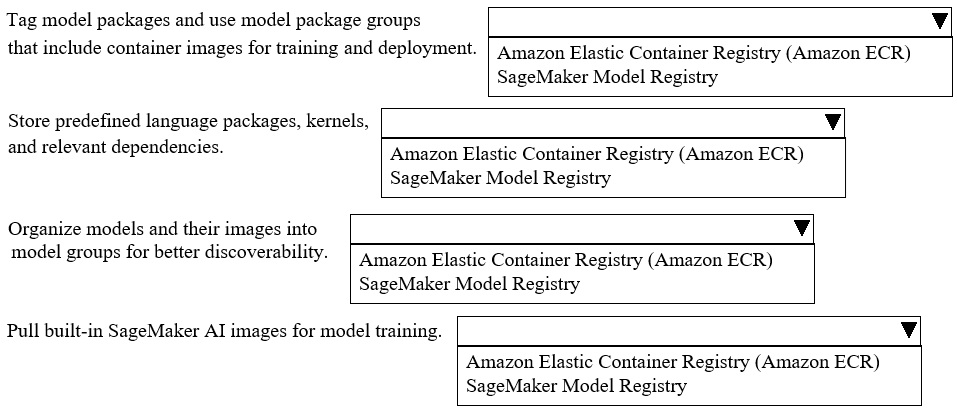
A company uses Amazon SageMaker AI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Choose four.)
Show Answer
Correct Answer: SageMaker Model Registry
Amazon Elastic Container Registry (Amazon ECR)
SageMaker Model Registry
Amazon Elastic Container Registry (Amazon ECR)
Explanation: Model Registry manages model packages, versions, tags, and model package groups for discoverability. Amazon ECR stores and distributes container images, including predefined/built-in images and custom images with language packages, kernels, and dependencies.
Question 72
An ML engineer has trained an ML model by using Amazon SageMaker AI. The ML engineer determines that the model is overfitting and that the training data contains unnecessary features. The ML engineer must reduce the overfitting and the impact of the unnecessary features.
Which solution will meet these requirements?
A. Increase the number of training iterations. Retrain the model.
B. Apply L1 regularization to the training data. Retrain the model.
C. Decrease the number of training iterations. Retrain the model.
D. Use SageMaker Debugger to apply L1 regularization to the running model.
Show Answer
Correct Answer: B
Explanation: L1 regularization (Lasso) penalizes the absolute magnitude of feature weights, encouraging irrelevant feature coefficients to become zero. This helps perform implicit feature selection and reduces overfitting. Increasing iterations can worsen overfitting, decreasing iterations is early stopping but does not specifically address unnecessary features, and SageMaker Debugger is for monitoring/debugging rather than applying regularization.
$19
Get all 237 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.