Associate Data Practitioner Free Practice Questions
This is the free Google Associate Data Practitioner practice question bank —
50 of 90 total questions, each with a full explanation, free to
read with no signup required. Updated 2026-10-04.
Every answer is verified against official Google documentation —
see our methodology.
Question 1
You manage data at an ecommerce company. You have a Dataflow pipeline that processes order data from Pub/Sub, enriches the data with product information from Bigtable, and writes the processed data to BigQuery for analysis. The pipeline runs continuously and processes thousands of orders every minute. You need to monitor the pipeline's performance and be alerted if errors occur. What should you do?
A. Use Cloud Logging to view the pipeline logs and check for errors. Set up alerts based on specific keywords in the logs.
B. Use the Dataflow job monitoring interface to visually inspect the pipeline graph, check for errors, and configure notifications when critical errors occur.
C. Use Cloud Monitoring to track key metrics. Create alerting policies in Cloud Monitoring to trigger notifications when metrics exceed thresholds or when errors occur.
D. Use BigQuery to analyze the processed data in Cloud Storage and identify anomalies or inconsistencies. Set up scheduled alerts based when anomalies or inconsistencies occur.
Show Answer
Correct Answer: C
Explanation: Cloud Monitoring can track Dataflow metrics such as throughput, latency, and errors. Create alerting policies on relevant metrics so notifications are sent automatically when thresholds are exceeded or errors occur. The other options rely on manual inspection, fragile log keyword matching, or downstream data analysis rather than proactive pipeline monitoring.
Question 1
Following a recent company acquisition, you inherited an on-premises data infrastructure that needs to move to Google Cloud. The acquired system has 250 Apache Airflow directed acyclic graphs (DAGs) orchestrating data pipelines. You need to migrate the pipelines to a Google Cloud managed service with minimal effort. What should you do?
A. Create a Google Kubernetes Engine (GKE) standard cluster and deploy Airflow as a workload. Migrate all DAGs to the new Airflow environment.
B. Create a Cloud Data Fusion instance. For each DAG, create a Cloud Data Fusion pipeline.
C. Create a new Cloud Composer environment and copy DAGs to the Cloud Composer dags/ folder.
D. Convert each DAG to a Cloud Workflow and automate the execution with Cloud Scheduler.
Show Answer
Correct Answer: C
Explanation: Cloud Composer is Google Cloud’s managed Apache Airflow service. Creating a Composer environment and placing the existing DAGs in its `dags/` folder is the most direct migration path, typically requiring far less effort than rewriting the pipelines or operating Airflow on GKE.
Question 1
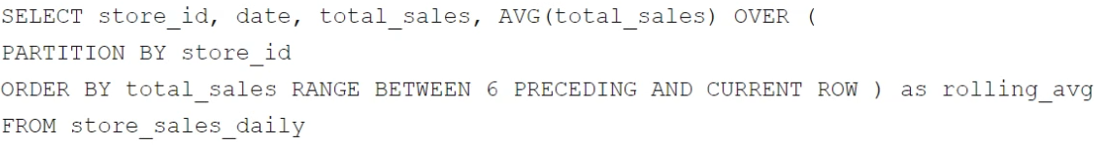
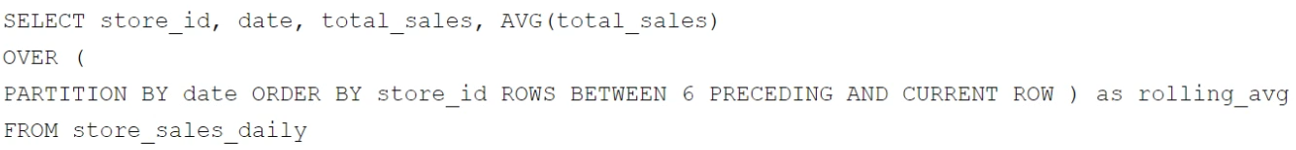
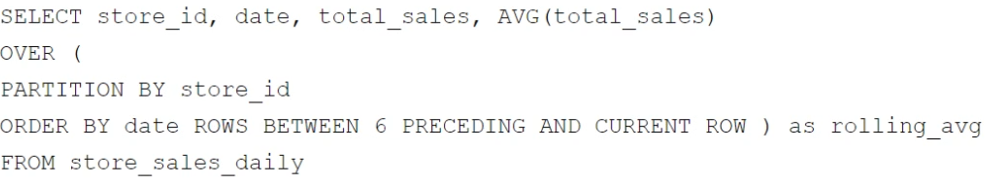
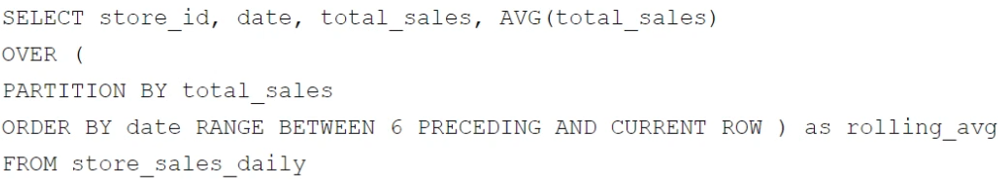
Your company has several retail locations. Your company tracks the total number of sales made at each location each day. You want to use SQL to calculate the weekly moving average of sales by location to identify trends for each store. Which query should you use?
A.
-------------------------
B.
-------------------------
C.
-------------------------
D.
-------------------------
Show Answer
Correct Answer: C
Explanation: Partitioning by store_id calculates each location’s average separately. Ordering by date and using ROWS BETWEEN 6 PRECEDING AND CURRENT ROW averages seven consecutive daily records.
Question 2
You work for a healthcare company. You have a daily ETL pipeline that extracts patient data from a legacy system, transforms it, and loads it into BigQuery for analysis. The pipeline currently runs manually using a shell script. You want to automate this process and add monitoring to ensure pipeline observability and troubleshooting insights. You want one centralized solution, using open-source tooling, without rewriting the ETL code. What should you do?
A. Create a Cloud Run function that runs the pipeline daily. Monitor the function's execution using Cloud Monitoring.
B. Configure Cloud Dataflow to implement the ETL pipeline, and use Cloud Scheduler to trigger the Dataflow pipeline daily. Monitor the pipeline's execution using the Dataflow job monitoring interface and Cloud Monitoring.
C. Use Cloud Scheduler to trigger a Dataproc job to execute the pipeline daily. Monitor the job's progress using the Dataproc job web interface and Cloud Monitoring.
D. Create a direct acyclic graph (DAG) in Cloud Composer to orchestrate a pipeline trigger daily. Monitor the pipeline's execution using the Apache Airflow web interface and Cloud Monitoring.
Show Answer
Correct Answer: D
Explanation: Cloud Composer is managed Apache Airflow, an open-source orchestration tool. A DAG can schedule the existing shell script (for example, with a BashOperator) without rewriting the ETL logic, while Airflow’s UI provides execution history and logs and Cloud Monitoring adds monitoring and alerting.
Question 2
You are designing an application that will interact with several BigQuery datasets. You need to grant the application's service account permissions that allow it to query and update tables within the datasets, and list all datasets in a project within your application. You want to follow the principle of least privilege. Which pre-defined IAM role(s) should you apply to the service account?
A. roles/bigquery.jobUser and roles/bigquery.dataOwner
B. roles/bigquery.connectionUser and roles/bigquery.dataViewer
C. roles/bigquery.admin
D. roles/bigquery.studioUser and roles/bigquery.filtereddataViewer
Show Answer
Correct Answer: A
Explanation: BigQuery Job User allows the service account to run query jobs. BigQuery Data Owner provides access to manage and update dataset contents and enumerate datasets. The other choices either lack the required write access or grant broader or unrelated permissions.
Question 3
You work for a gaming company that collects real-time player activity data. This data is streamed into Pub/Sub and needs to be processed and loaded into BigQuery for analysis. The processing involves filtering, enriching, and aggregating the data before loading it into partitioned BigQuery tables. You need to design a pipeline that ensures low latency and high throughput while following a Google-recommended approach. What should you do?
A. Use Cloud Composer to orchestrate a workflow that reads the data from Pub/Sub, processes the data using a Python script, and writes it to BigQuery.
B. Use Dataflow to create a streaming pipeline that reads the data from Pub/Sub, processes the data, and writes it to BigQuery using the streaming API.
C. Use Dataproc to create an Apache Spark streaming job that reads the data from Pub/Sub, processes the data, and writes it to BigQuery.
D. Use Cloud Run functions to subscribe to the Pub/Sub topic, process the data, and write it to BigQuery using the streaming API.
Show Answer
Correct Answer: B
Explanation: Use Dataflow for a low-latency, high-throughput streaming pipeline from Pub/Sub to BigQuery. It supports the required filtering, enrichment, and aggregation, and can write results to partitioned BigQuery tables. Cloud Composer is an orchestrator, while Dataproc and Cloud Run functions are less suitable for this managed streaming workload.
Question 3
Your organization is conducting analysis on regional sales metrics. Data from each regional sales team is stored as separate tables in BigQuery and updated monthly. You need to create a solution that identifies the top three regions with the highest monthly sales for the next three months. You want the solution to automatically provide up-to-date results. What should you do?
A. Create a BigQuery table that performs a UNION across all of the regional sales tables. Use the ROW_NUMBER() window function to query the new table.
B. Create a BigQuery table that performs a CROSS JOIN across all of the regional sales tables. Use the RANK( ) window function to query the new table.
C. Create a BigQuery materialized view that performs a UNION across all of the regional sales tables. Use the RANK() window function to query the new materialized view.
D. Create a BigQuery materialized view that performs a CROSS JOIN across all of the regional sales tables. Use the ROW_NUMBER() window function to query the new materialized view.
Show Answer
Correct Answer: C
Explanation: UNION combines the regional tables’ sales rows for comparison, while a materialized view keeps the combined data up to date as the source tables change. Applying RANK() to the combined results identifies the top regions each month; a CROSS JOIN would incorrectly create combinations of rows.
Question 4
Your company stores historical data in Cloud Storage. You need to ensure that all data is saved in a bucket for at least three years. What should you do?
A. Set temporary object holds.
B. Set a bucket retention policy.
C. Change the bucket storage class to Archive.
D. Enable Object Versioning.
Show Answer
Correct Answer: B
Explanation: Set a bucket retention policy with a three-year retention period. It prevents objects from being deleted or replaced until the retention period expires.
Question 4
You have an existing weekly Storage Transfer Service transfer job from Amazon S3 to a Nearline Cloud Storage bucket in Google Cloud. Each week, the job moves a large number of relatively small files. As the number of files to be transferred each week has grown over time, you are at risk of no longer completing the transfer in the allocated time frame. You need to decrease the total transfer time by replacing the process. Your solution should minimize costs where possible. What should you do?
A. Create parallel transfer jobs using include and exclude prefixes.
B. Create a transfer job using the Google Cloud CLI, and specify the Standard storage class with the --custom-storage-class flag.
C. Create a batch Dataflow job that is scheduled weekly to migrate the data from Amazon S3 to Cloud Storage.
D. Create an agent-based transfer job that utilizes multiple transfer agents on Compute Engine instances.
Show Answer
Correct Answer: A
Explanation: Create multiple Storage Transfer Service jobs and partition the source data with non-overlapping include/exclude prefixes. Running transfers in parallel can reduce the total time for a workload with many small files without requiring additional Compute Engine agents or a separate Dataflow pipeline.
Question 5
You are working with a large dataset of customer reviews stored in Cloud Storage. The dataset contains several inconsistencies, such as missing values, incorrect data types, and duplicate entries. You need to clean the data to ensure that it is accurate and consistent before using it for analysis. What should you do?
A. Use the PythonOperator in Cloud Composer to clean the data and load it into BigQuery. Use SQL for analysis.
B. Use BigQuery to batch load the data into BigQuery. Use SQL for cleaning and analysis.
C. Use Storage Transfer Service to move the data to a different Cloud Storage bucket. Use event triggers to invoke Cloud Run functions to load the data into BigQuery. Use SQL for analysis.
D. Use Cloud Run functions to clean the data and load it into BigQuery. Use SQL for analysis.
Show Answer
Correct Answer: B
Explanation: Batch load the files into BigQuery, then use SQL to handle missing values, correct data types, and remove duplicates before analysis. BigQuery scales these transformations efficiently, while the other options add unnecessary orchestration or data movement.
$19
Get all 90 questions with detailed answers and explanations
Instant download HTML + PDF delivered the moment payment clears.
Secure Stripe checkout we never see or store your card details.
7-day refund if files are defective see our refund policy.